
 DevPixel Engineering
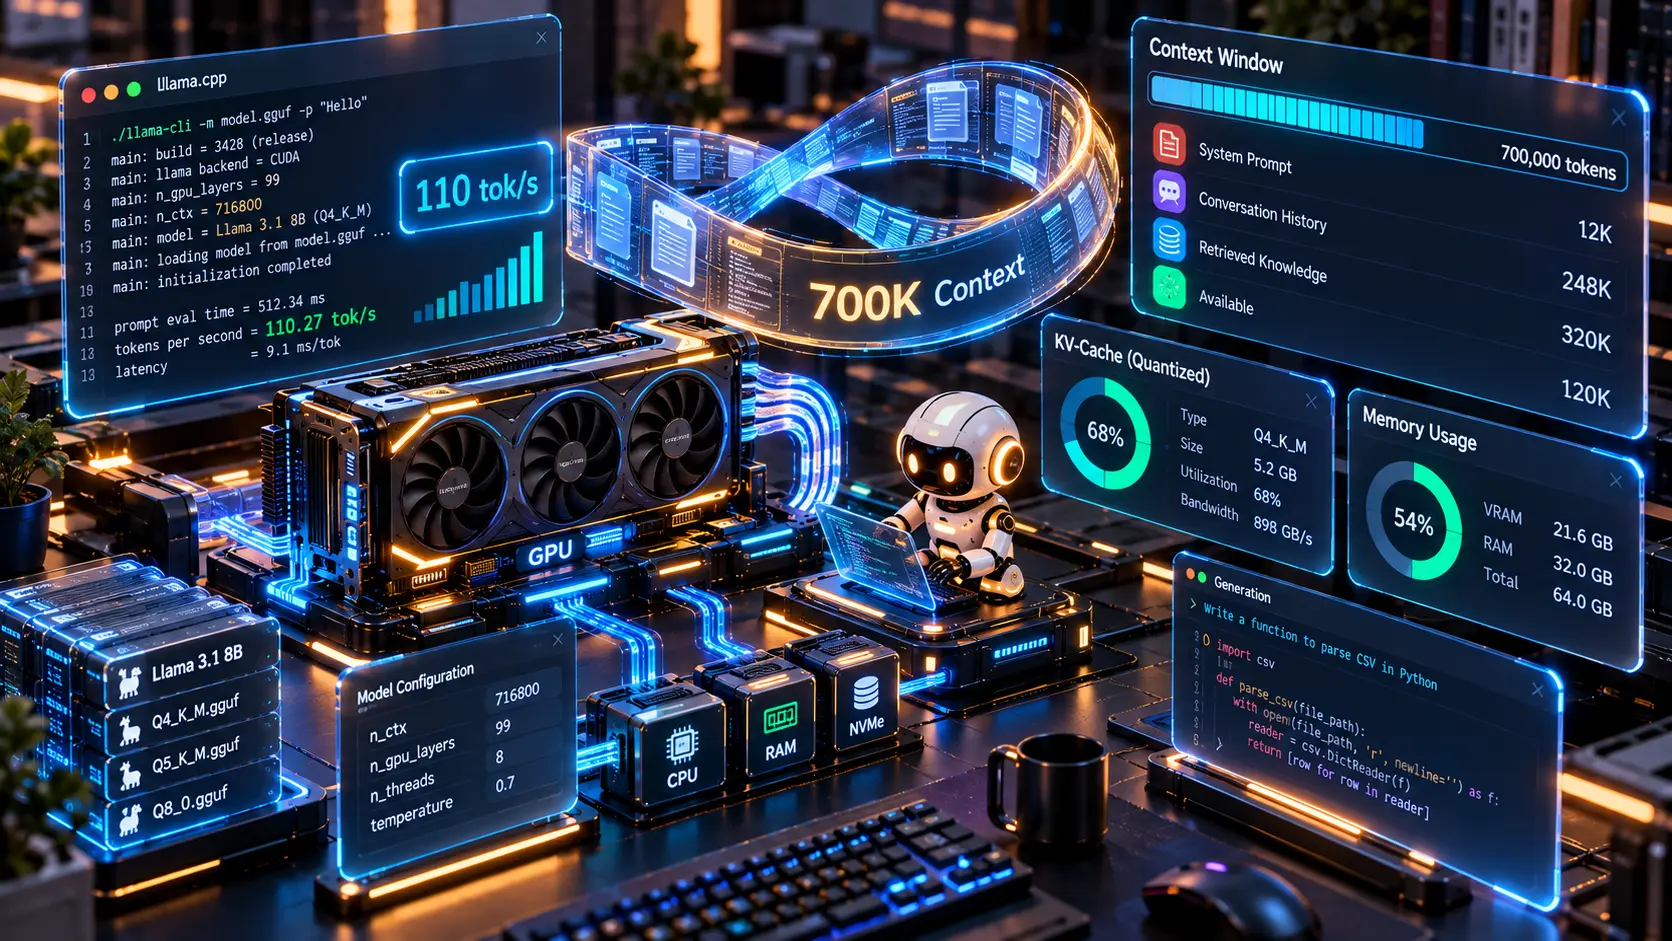
In an era where state-of-the-art language models natively accept context windows spanning hundreds of thousands or millions of tokens, the critical operational challenge for local deployment engineers is no longer raw model parameter size, but the memory footprint and generation latency of the Key-Value (KV) Cache. Once context exceeds 100K tokens, naive attention computation exhausts available GPU VRAM and collapses throughput to single-digit tokens per second.
Recent community breakthroughs have demonstrated sustained local inference on models like Qwen 3.8 Flash running across 700K token continuous contexts without session compaction on workstation-grade hardware. This capability is anchored by three architectural optimizations: modern FlashAttention kernels, Sliding Window Attention (SWA), and quantized KV SmartCache architectures.
Memory consumption of the KV Cache scales linearly with token sequence length. At 700K tokens in uncompressed FP16 representation, the KV cache alone demands upwards of 40GB of VRAM — exceeding standard consumer cards without aggressive cache quantization.
1. The Technical Trifecta for Extreme Contexts
Maintaining generation speeds beyond 100 tokens/second at 700K token depths requires three coordinated optimizations:
- KV Cache Quantization: Compressing keys and values from 16-bit floats to 8-bit or 4-bit representations (such as q8_0 or q4_0 in llama.cpp), recovering up to 75% VRAM capacity with minimal perplexity degradation.
- Sliding Window Attention (SWA): Constraining attention calculations to localized token neighborhoods coupled with dedicated attention sinks to preserve global semantic coherence.
- Prompt Caching & Memory Tiering: Persisting tokenized repository state in system DDR5 RAM and streaming active working sets into fast GPU VRAM only as active execution requires.
2. Production Configuration with llama.cpp
When configuring local inference servers to digest massive code repositories, engineers should optimize runtime flags:
Read next: Automating Code Review When AI Writes Over 90% of the Codebase
Conclusion
Mastering extreme context optimization on local infrastructure liberates engineering teams from external cloud dependencies, preserves complete intellectual property privacy, and turns local workstations into high-performance repository intelligence hubs.
Chưa có bình luận nào. Hãy là người đầu tiên chia sẻ góc nhìn!