
 DevPixel Engineering
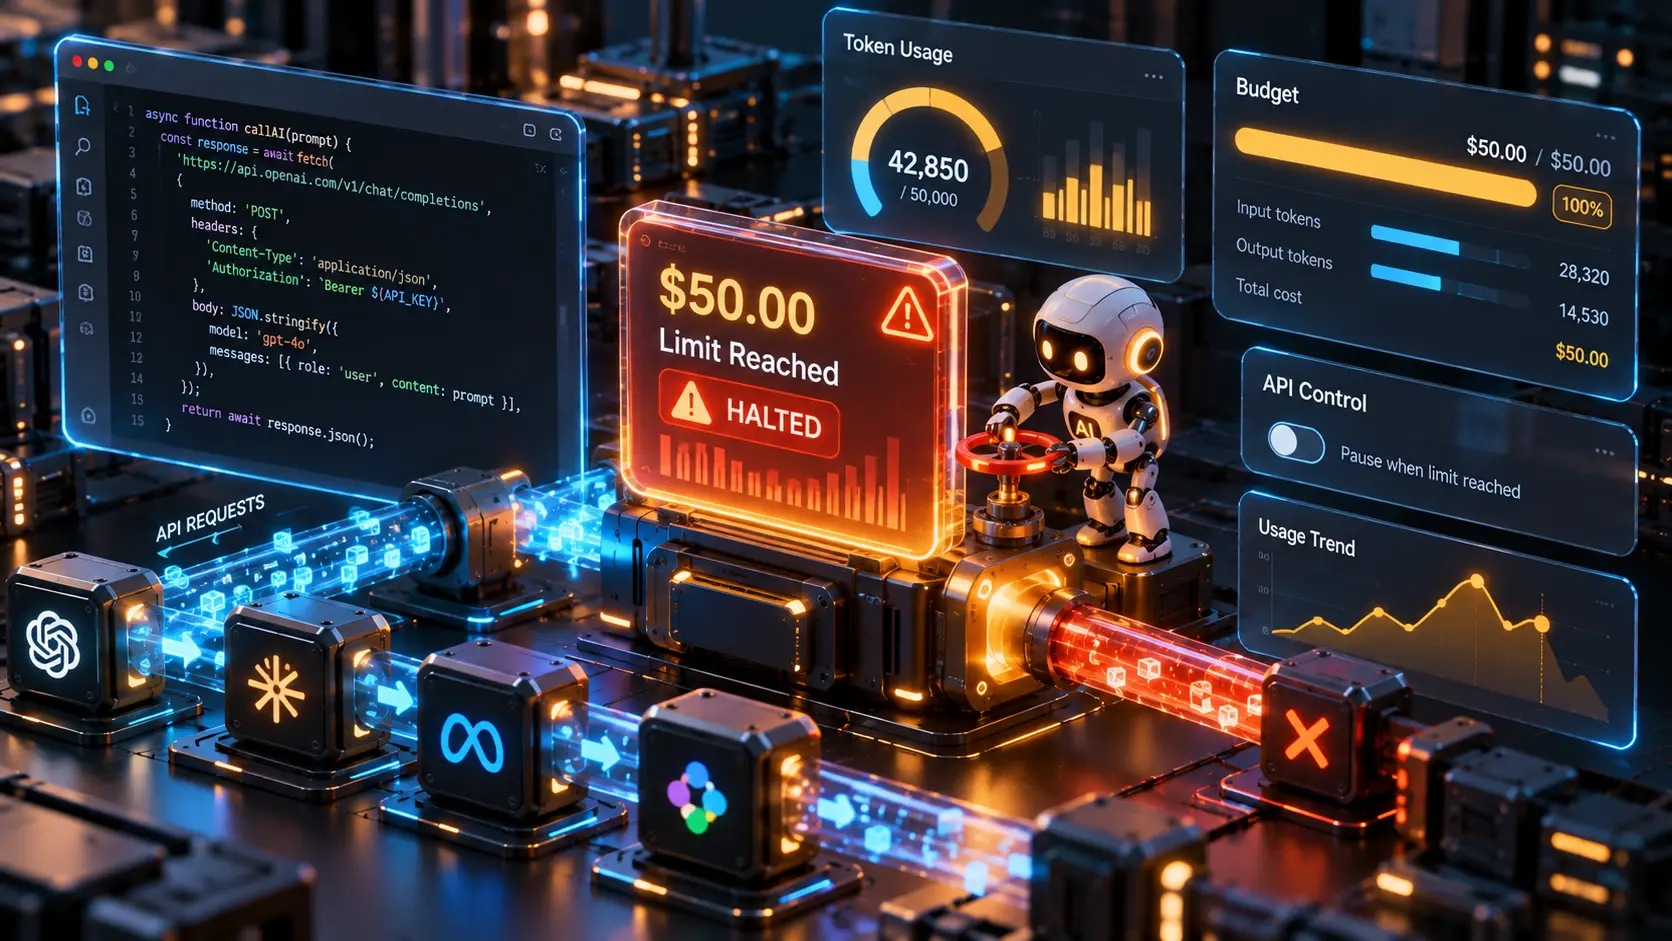
When integrating autonomous AI coding agents like Claude Code, Cursor, or OpenDevin into engineering pipelines, one of the most perilous operational hazards is the infinite reasoning loop. When an agent confronts an unresolvable edge case or repeated test failure, it can programmatically query APIs hundreds of times within minutes, racking up thousands of dollars in usage before anyone notices.
Simon Willison, co-creator of Django and prominent AI systems researcher, highlighted this urgent requirement: “We are entering a phase where every AI service and autonomous tool must implement Default Hard Budget Caps by design.”
A soft warning email sent when spending breaches a threshold is completely futile against high-throughput agent execution. Autonomous agent infrastructure demands hardware-grade circuit breakers that terminate execution instantly when spending caps are met.
1. The Critical Difference Between Soft and Hard Budget Caps
Most cloud providers and API gateways historically defaulted to soft alerting thresholds: when usage crosses a spending milestone, an automated notification is queued. However, in continuous autonomous development:
- Email alerts suffer delivery latency ranging from 15 to 60 minutes. During that lag, an agent trapped in a retry loop can burn millions of reasoning tokens.
- Modern reasoning models carry significantly higher per-token pricing, multiplying financial exposure rapidly.
- Hard Budget Caps represent deterministic enforcement: the moment a balance or task quota is exhausted, subsequent requests receive immediate HTTP 429 or 402 rejections at the gateway level.
2. The 3-Tier Budget Protection Architecture
To safely scale autonomous engineering agents, development organizations should implement a layered defensive architecture:
Layer 1: Local Task-Level Circuit Breakers
Every isolated agent execution should receive a deterministic token and iteration budget. If an agent fails to achieve passing criteria within its pre-allocated scope, it must abort gracefully and surface telemetry to a human engineer.
Layer 2: Centralized Quota Gateways
Rather than distributing master provider credentials across individual developer environments, route all requests through an intermediary gateway (such as LiteLLM or Cloudflare AI Gateway):
- Provision scoped virtual keys per engineer and repository with strict daily expenditure limits.
- Enforce hard cutoffs immediately upon quota exhaustion without modifying client agent code.
- Log fine-grained token economics to accurately calculate engineering ROI across projects.
Layer 3: Provider-Level Spend Limits
Within provider consoles, disable automatic balance reload unless accompanied by real-time monitoring webhooks. Pre-fund accounts with fixed capital allocations to cap total financial liability in worst-case failure scenarios.
Read next: Automating Code Review When AI Writes Over 90% of the Codebase
Conclusion
Implementing hard budget caps does not restrict developer velocity. Instead, it provides the essential safety rails that empower engineering organizations to scale autonomous AI adoption with confidence and fiscal predictability.
Chưa có bình luận nào. Hãy là người đầu tiên chia sẻ góc nhìn!