
 DevPixel Engineering
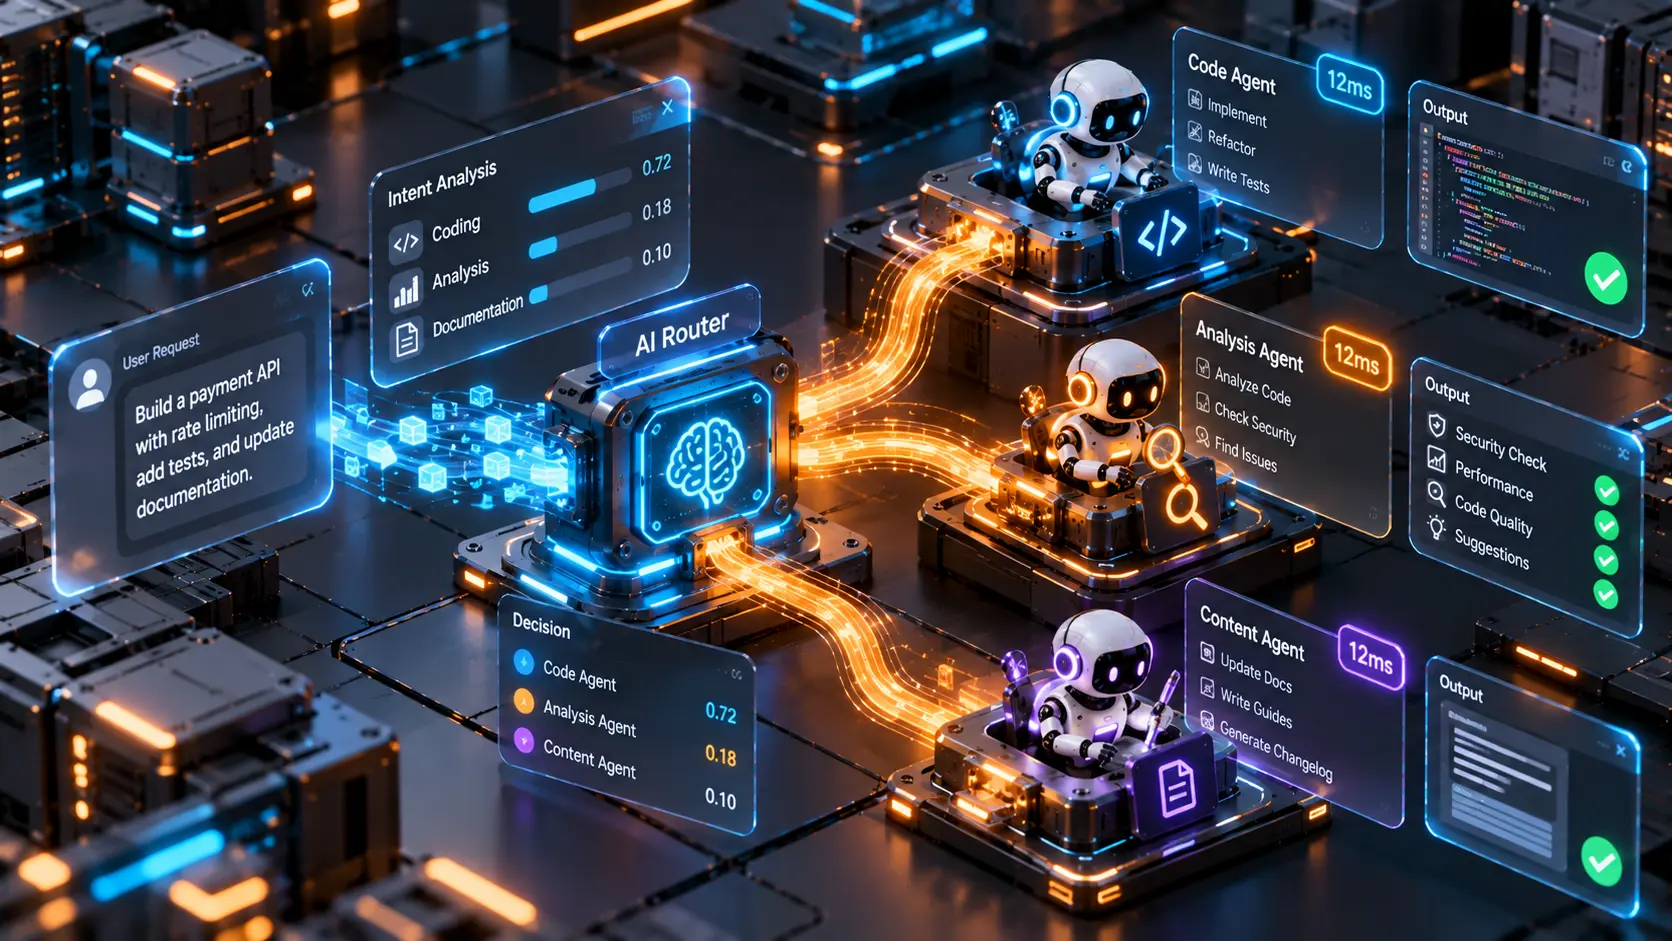
Within modern multi-agent systems, one of the most frustrating bottlenecks undermining user experience and inflating cloud infrastructure cost is routing latency. Traditionally, when an incoming prompt arrives, architectures dispatch requests to a large generative language model merely to generate natural language explanations or JSON payloads to decide which downstream worker should handle the task.
The emergence of System One models (also recognized as Decision Models) completely restructures this workflow. Rather than generating autoregressive natural language text, these architectures are specifically tuned to output raw probability vectors, discrete categorical classifications, and calibrated confidence scores in single-digit milliseconds.
Grounded in Daniel Kahneman’s cognitive framework, System 1 represents immediate reflex and rapid classification, while System 2 encompasses deliberate, sustained reasoning. Deploying expensive System 2 reasoning models for low-complexity routing gates represents immense engineering waste.
1. Generative LLMs vs. Decision Models
Standard generative models are architected for sequential token prediction. When leveraged as multi-agent routers:
- They generate textual responses (e.g.,
{"route": "database_engineer"}), incurring latency penalties between 200ms and 1,500ms before initial dispatch. - They introduce parsing fragility, susceptible to formatting hallucinations or extraneous conversational prose.
- Decision Models: Consume raw text representations but terminate in classification prediction heads, directly exporting calibrated numeric arrays in 5ms to 25ms with 90% reduced compute overhead.
2. Production Applications in Multi-Agent Pipelines
In distributed agent orchestration (such as the architecture detailed in the 4-Agent Pipeline in Claude Code), Decision Models fulfill three high-throughput mandates:
- Ultra-Low-Latency Intent Dispatch: Deterministically routing user prompts between retrieval engines (RAG), code generation pipelines, or administrative tools.
- Deterministic Safety Guardrails: Evaluating prompt-injection and policy compliance in near-zero runtime before engaging upstream frontier models.
- Outcome Evaluation (Reward Scoring): Rapidly evaluating and scoring candidate generations across multi-agent deliberations to select optimal responses.
Read next: Integrating gstack with Claude Code: Complete Installation and Optimization Guide
Conclusion
Pairing rapid System 1 Decision Models for millisecond-level routing with deep System 2 reasoning engines for complex execution defines the frontier architecture for highly responsive, cost-effective enterprise AI platforms.
Chưa có bình luận nào. Hãy là người đầu tiên chia sẻ góc nhìn!